On This Page· 4
You ask for a weekend guide to Kyoto. The AI returns five options. Your top pick—a specific tea ceremony in Arashiyama—is missing. There is no explanation. No warning. Just silence.
Most travelers assume this is a flaw in the ranking algorithm, a mysterious score where their favorite activity simply placed too low. That assumption is incorrect. Research on AI travel guides reveals that exclusion is rarely about popularity scores. It is about constraint failure. The activity was not ranked out; it was filtered out because it failed a specific check the system was actively tracking. Understanding this shift from mystery to mechanism is critical for anyone relying on these tools for personalized itineraries.
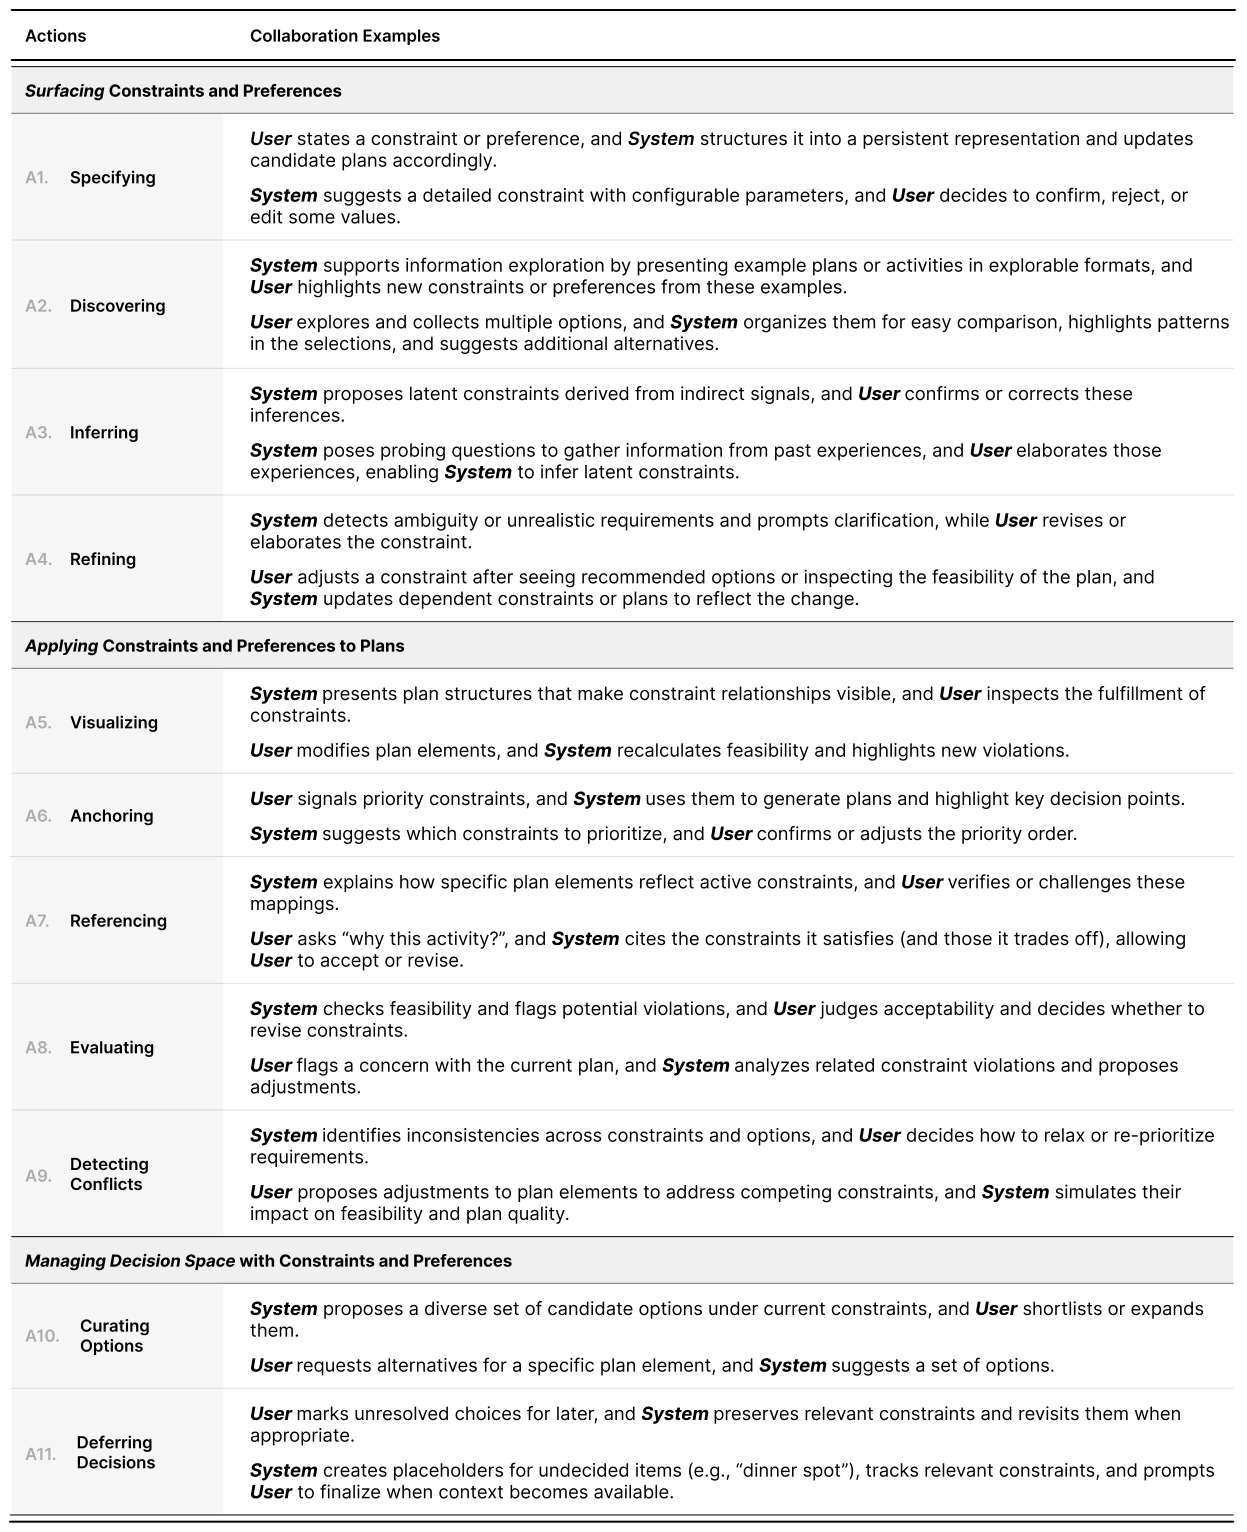
The 3 constraint classes that filter every AI travel guide
When an AI travel guide excludes a specific activity, it is rarely a matter of popularity or generic preference. Instead, the system evaluates the option against three distinct constraint classes. These classes function as sequential filters, each with a different source and level of rigidity.
External, Internal, and Integrative
The first class is External Factors. These are destination-specific constraints that exist regardless of who is traveling. They include the availability of accommodations, specific attractions, seasonal events, and transportation schedules. For instance, whale-watching tours only operate during certain months; this is an external reality the AI must respect.
The second class consists of Internal Factors. These are personal to the traveler, including travel companions, the purpose of the trip, past experiences, and individual likes or dislikes. Two people visiting the same city will have divergent internal factors, leading to different itineraries even if the external landscape is identical.
The third class involves Integrative Factors, which relate to the structure and coherence of the plan. This includes how activities interconnect, fixed temporal or spatial anchors like flight times, and the overall rhythm of the day, such as balancing high-energy hikes with low-effort museum visits.
A Specific Failure Case
Consider a traveler interested in whale-watching. This activity passes the external check: it exists in the destination and is in season. However, it can still be dropped by the AI if it fails the other two checks. If the traveler dislikes boats, the activity fails the internal filter. Alternatively, if the activity requires three hours but the traveler has only allocated a two-hour window for that part of the day, it fails the integrative check. Understanding these distinct categories helps explain why AI recommendation algorithms prioritize structural fit and explicit constraints over simple keyword matching.
Why AI drops activities that fail hard logistical filters
Logistical barriers in AI travel guides act as binary switches, not weighted scores. A constraint is a rule that must be satisfied for an activity to remain in the candidate pool. When a specific limit is breached, the system removes the option immediately, regardless of how well it matches other criteria.
Hard versus soft filters
Hard filters include objective, quantifiable limits such as time availability, budget caps, and operational availability. If an excursion costs $150 and your stated budget is $100, it is excluded. Soft filters, by contrast, involve subjective preferences like comfort levels, aesthetic taste, or personal interest in a specific theme. While soft filters influence the order of results, they rarely trigger automatic deletion. A hotel with a slightly quieter location might rank lower, but it will not vanish unless it violates a hard rule like the number of guests or check-in times.
Current AI systems treat logistical constraints as absolute barriers, meaning that if an activity exceeds a stated time or budget threshold, it is dropped from the list entirely. The system does not attempt to balance a high-interest match against a minor logistical overrun; the hard filter takes precedence. This behavior explains why a perfectly aligned activity might be missing from your results simply because it required 45 minutes of transit when you specified a 30-minute maximum.
The inference gap
A significant source of confusion lies in how these systems handle unstated constraints. Human planners often negotiate limits implicitly, but AI models typically wait for explicit input. If you do not specify a maximum transit time, the algorithm has no basis to exclude activities with longer travel durations. Conversely, if you do specify a limit, the system applies it strictly. This lack of inference creates a gap between user expectation and system output. Users often assume the AI understands their general tolerance for commutes, but the model requires clear data points to function correctly. Without explicit parameters, the AI may include options that feel irrelevant to your actual routine, or exclude viable ones due to overly strict default assumptions. Clarifying these logistical boundaries in your prompt is essential to align the algorithm’s filtering logic with your real-world needs.
The gap: AI tracks explicit inputs, not implied preferences
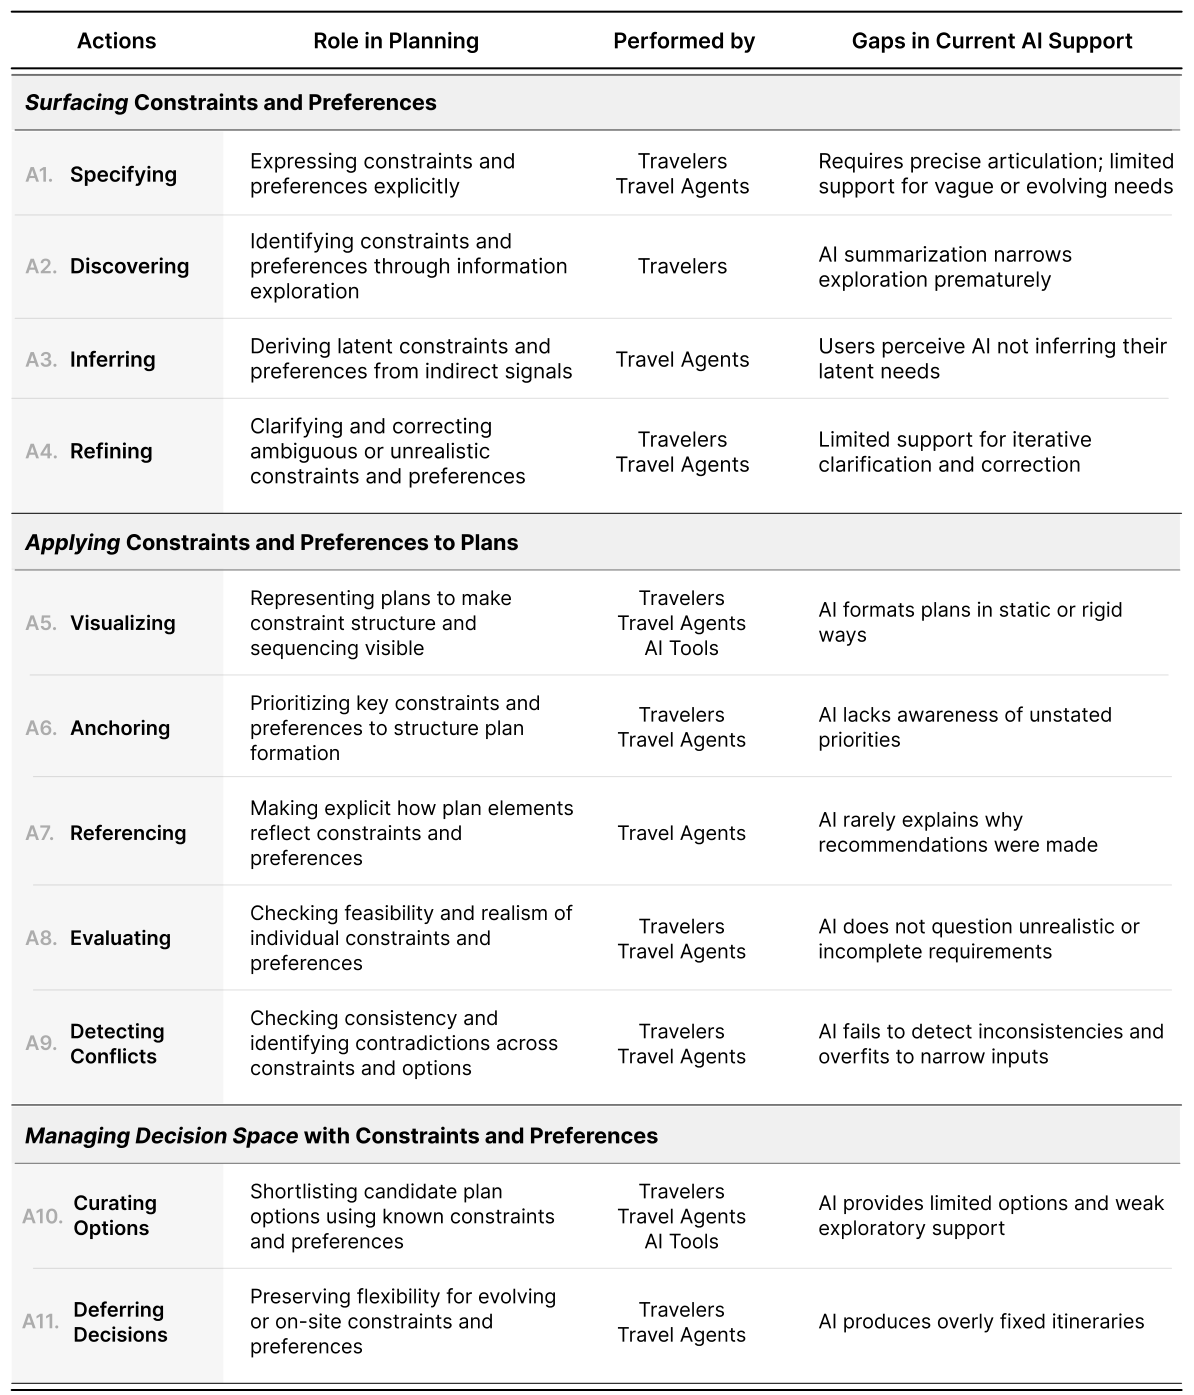
Human travel agents do not wait for a perfect prompt. They ask about past trips, infer interests from vague descriptions, and treat ambiguity as a conversation starter rather than a data error. This in-situ refinement allows them to surface hidden preferences that a user might not even realize they hold. A human agent might ask, “Do you prefer forest hikes or coastal walks?” to clarify a broad interest in “nature,” ensuring the recommendation matches the traveler’s specific definition. AI systems, however, typically lack this dialogue mechanism.
When a constraint is ambiguous, current AI tools rarely engage in clarifying questions or conflict resolution. Instead, they select an interpretation and move on, often silently excluding options that conflict with their chosen path. This behavior means that if a user’s input is slightly off-target, the resulting guide may miss key activities without providing any explanation for the exclusion. The AI does not flag the conflict; it simply resolves it by omission, leaving the user to guess why a preferred activity is missing.
This leads to the one-shot nature of most AI recommendation algorithms. The system generates a list based on the initial prompt and ends the interaction. There is no iterative refinement loop where the AI suggests options, the user reacts, and the system adjusts in real-time. Without this feedback cycle, the AI cannot uncover unstated logistical constraints or nuanced taste preferences. The result is a static list that reflects only what was explicitly stated, not the complex web of implicit preferences that actually shape a good travel experience.
FAQ: Why is my preferred activity missing from the AI guide?
Does the AI rank activities by popularity or score?
No. AI travel guides operate on constraint filtering, not popularity rankings. Even a highly-rated attraction is dropped if it violates a logistical limit (time, budget) or a preference constraint inferred from your prompt.
How can I identify the specific cause of the exclusion?
Current AI recommendation algorithms rarely provide transparency into why an item was filtered out. You typically must reverse-engineer the answer by cross-referencing your inputs against the missing activity’s requirements to spot the conflicting parameter.
Can I fix this to recover the missing activity?
Yes, by clarifying trade-offs in your next prompt. Instead of vague interests, specify concrete boundaries—e.g., “I can allocate 2 hours to this” or “I prefer hiking over museums.” This explicit guidance helps the AI balance conflicting constraints more effectively.
Inclusion in an AI travel guide is a matter of constraint satisfaction, not popularity ranking. Your preferred activity didn’t lose to a better score; it failed a specific logistical or preference check that the system was actively tracking. As research suggests, future AI systems will likely support more collaborative planning, turning the silent exclusion of options into a transparent dialogue between user and system. Until then, the question remains: do we adapt our prompts to fit the current rigid logic of these models, or do we wait for the technology to eventually grasp the messy, implicit complexity of human travel?